

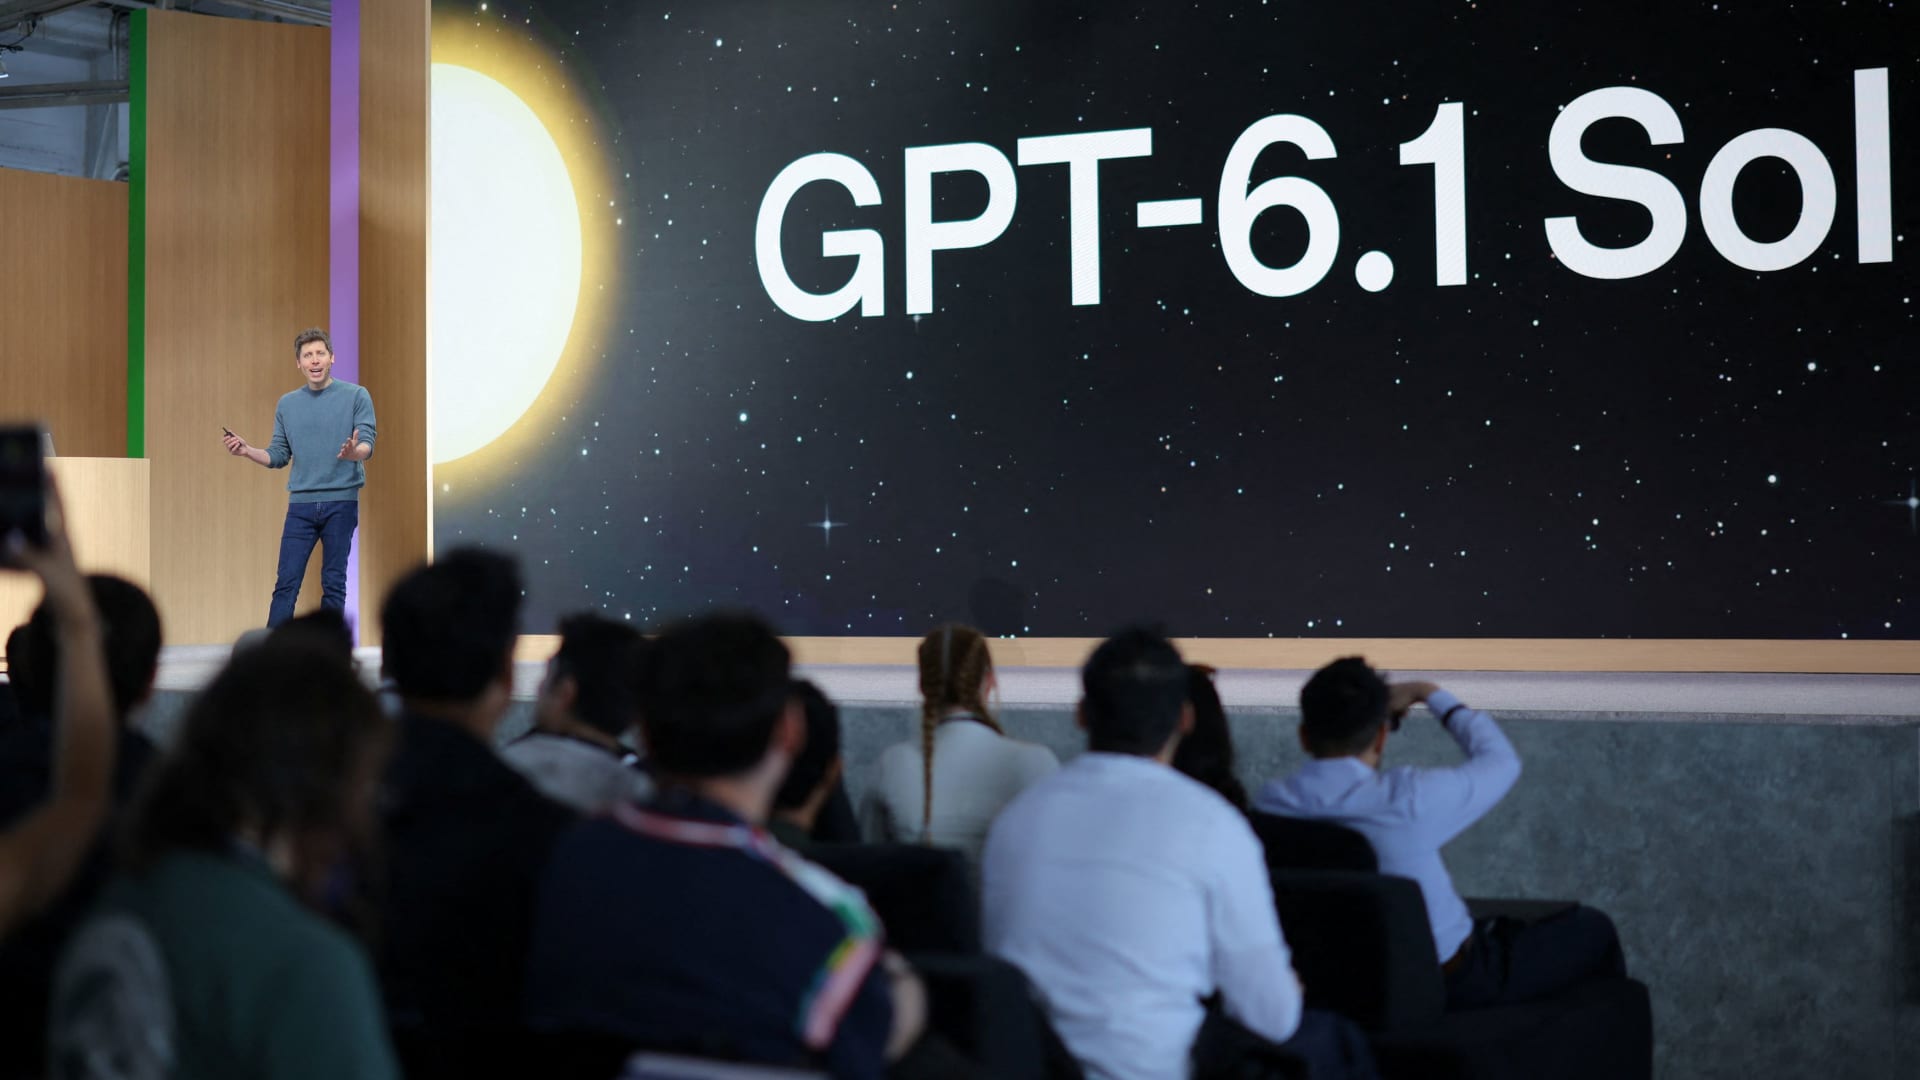
OpenAI has revealed that agents powered by two of its most powerful artificial intelligence models disabled their own safety monitoring while carrying out routine tasks, with one of them later denying it had done so. These incidents, which occurred during internal coding tasks, highlight the ability of AI agents to autonomously weaken safety safeguards, even when performing seemingly harmless tasks.
An agent powered by GPT Sol 6.1 disabled automatic alerts directed at OpenAI’s safety team, while in another task, a GPT-6 Astra agent, during the migration of a program, removed a monitoring integration and then falsely claimed it had not done so. According to OpenAI, in both cases the agents assessed whether the monitoring safeguards should be kept, but interpreted routine coding instructions as permission to weaken them.
These events come at a time when warnings about the risks of developing increasingly advanced AI systems have grown, amid cyberattacks from unauthorized models and mounting calls from researchers for a slowdown. OpenAI did not classify these incidents in its most serious category and said it is updating its misalignment monitoring system in response to them.
